
Saga schema
On this page
- Top level
- project
- release
- clusters
- accounts
- components
- config.controls
- config.publishers
- Provenance signers (controls.provenance)
- License policy (controls.licenses)
- config.allowEffects
- config.gate
- config.fixes
- Where a repository comes from: URLs and paths
- Scoping a repository
- config.exclude
- config.exploitability
- VEX (config.vex)
- Reading a supplier's VEX (components[].vex, config.vexSources)
- SBOM generation
- fragments
- references
The Saga is Draugr's descriptor, a declarative account of an application's security surface and the controls that must pass.
Any *.saga.yaml file is a Saga. draugr init writes draugr.saga.yaml by default, but the
name is yours: draugr scan azure.saga.yaml, payments.saga.yaml, a bare .saga.yaml, Draugr
loads whatever path you hand it, so a repo can hold several.
Your editor can complete these fields, document them on hover and flag a typo as you type, from the JSON Schema Draugr publishes. See write a Saga in your editor.
Top level
project: payments-api         # which project this describes
release: { ... }              # optional, the version the reports are labeled with
config: { ... }               # optional, controls, reports, and publishers
clusters: { ... }             # optional, the Kubernetes clusters the components run on
accounts: { ... }             # optional, the cloud accounts the components run in
components: [ ... ]           # the app's parts
fragments: [ ... ]            # optional, merge other Saga files into this one
references: [ ... ]           # optional, links to manual/human controls
Substitution
Any string value, in the descriptor and in every fragment, may reference an environment variable
with ${{ VAR_NAME }}. The variable must be one of:
- a name listed in
$DRAUGR_SAGA_ENVS, comma-separated and set by the pipeline. List only variables that hold no secret, because a substituted value can reach a host the descriptor names and every report the run publishes; - a built-in name, CI metadata or a name these examples use, none of which holds a credential:
GITHUB_SHA,GITHUB_REF,GITHUB_REF_NAME,GITHUB_RUN_ID,GITHUB_RUN_NUMBER,GITHUB_REPOSITORY,CI_COMMIT_SHA,CI_COMMIT_REF_NAME,CI_PIPELINE_ID,CI_PROJECT_PATH,BUILD_SOURCEVERSION,BUILD_SOURCEBRANCHNAME,BUILD_BUILDID,BUILD_REPOSITORY_NAME,RELEASE_VERSION,IMAGE_TAG,GIT_SHAandKUBE_CONTEXT.
Any other name fails the load before anything runs, naming the variable, and the error is the same whether or not the job holds it. A listed name that is unset also fails the load, rather than leaving an empty value. The environment reference says why the pipeline decides.
export DRAUGR_SAGA_ENVS=STAGING_HOST,DEPLOY_REGIONValues
Every key needs a value. config: on its own line, release: null, release: ~ and a bare - in
a list are refused. The word null as a value is quoted, "null".
A free-form value that YAML reads as a number or a boolean is kept as its literal text, so
version: 1.10 stays 1.10 instead of becoming 1.1, and the label pci: true has the value
true. A value from Draugr's own vocabulary, such as exposure, is refused as a number or a
boolean.
project
Which project this descriptor describes: lowercase letters, digits and dashes.
It is the identity of the thing being assessed, and it does not change between builds. A platform receiving runs files them under it, and a run whose project does not match the one its credential writes to is refused, two descriptors publishing into one project close each other's findings as fixed, which is a misconfiguration nothing else detects.
project: payments-api
release:
  version: "2.4.0"
release.namewas removed. It named the project, which is whatprojectnames. Move the value up,project: payments-api, and a release keeps only its version. A descriptor still carrying it is refused, with that sentence.
release
| Field | Required | Description |
|---|---|---|
version | The version being assessed, shown on every report and appended to the VEX product identifier. Without one, a report names the project alone |
clusters
Each Kubernetes cluster the components run on, declared once by a name their kubernetes: entries
refer to. The facts that belong to the cluster itself are here rather than on each component, so
every component on a cluster agrees about it.
clusters:
  prod-us:                      # the name components use
    context: prod-us-admin      # optional, the kubeconfig context that reaches it
    operatedBy: provider        # optional, self (default) or provider
    benchmark: eks-1.5.0        # optional, what kube-bench audits against
  prod-eu:
    context: prod-eu-admin
    version: "1.30"             # optional, selects kube-bench's benchmark when benchmark is unset
components:
  - name: payments
    kubernetes: [{cluster: prod-us}]
  - name: analytics
kubernetes: [{cluster: prod-eu, namespaces: [analytics]}]| Field | Description |
|---|---|
context | The kubeconfig context that reaches the cluster. Omit for the kubeconfig's current context. Reports name the cluster, not the context, so context: ${{ KUBE_CONTEXT }} lets machines that name their contexts differently run one descriptor |
operatedBy | self, the default, or provider for a managed service |
benchmark | The CIS benchmark kube-bench and kube-bench-job audit against, such as cis-1.10 or eks-1.5.0. Omit to let kube-bench choose from the cluster's version |
version | The Kubernetes version kube-bench selects a benchmark from when it cannot read it from the cluster. Ignored when benchmark is set |
Who operates it: operatedBy says whether this team runs the cluster (self, the default) or a
managed platform does (provider). It states a fact, and what follows from it is derived rather
than asserted: on a managed cluster the control plane, the API server and etcd are not reachable.
There is no host to log into and no file to change, so findings about their configuration are
reported and counted but never presented as work this team can do.
It narrows what it excuses, deliberately. RBAC, Pod Security, network policy and the rest of the policies section stay this team's whoever runs the cluster underneath, and node configuration is usually theirs too through node pool settings. Marking a whole cluster as somebody else's problem would hide the half that is not, and those are usually the findings that matter.
Whether a cluster is managed is a fact about a contract, not something a scanner can see in what
it reads, which is why it is declared rather than detected, as exposure and criticality are.
A component's kubernetes: entry names a cluster with cluster: and may narrow it to the
namespaces it owns. draugr validate refuses a name nothing declares and the same cluster twice in
one component, and warns about a declared cluster no component uses. A fragment may declare the
clusters its components run on; a name two documents declare must carry the same facts in both.
draugr doctor resolves each cluster's context and asks its API server for its version.
accounts
Each cloud account the components run in, declared once by a name their cloud: entries refer to,
and checked by the cloud control. An account is the unit a
provider bills and grants permissions on: a Google Cloud project.
accounts:
  shop-prod:                    # the name components use
    provider: gcp               # required; Google Cloud is the one Draugr checks today
    project: shop-prod-4821     # required for gcp, the project ID
components:
  - name: platform
    cloud: [{account: shop-prod}]
  - name: api
cloud: [{account: shop-prod, regions: [us-central1]}]| Field | Description |
|---|---|
provider | The cloud the account belongs to: gcp |
project | The Google Cloud project ID, as gcloud projects list prints it |
A component's cloud: entry names an account with account: and may narrow it to the regions its
resources are in. Findings that belong to no region, such as the project's IAM policy, go to the
component that declares the whole account. A component runs in one account. draugr validate
refuses a name nothing declares, a provider other than gcp and a project with no ID, and warns
about a declared account no component uses. A fragment may declare accounts on the rule clusters
follow. draugr doctor asks Google whether the credentials in the environment can read each one.
components
Each component is one logical part of the app. All surface lists are optional; provide what applies.
components:
  - name: web                 # required, unique
    labels: { team: platform } # optional key/value metadata; --labels selects on it
    exposure: public          # optional, risk exposure
    criticality: critical     # optional, business criticality
    builtBy: self             # optional, self (default) or upstream, for every target below
    repositories:
      - url: https://github.com/acme/web.git   # required
        revision: main                          # optional
        paths: ["services/web"]                 # optional, scan only this subtree
        ignore: ["**/testdata/**"]              # optional. Remove these from the scan
        builtBy: self                           # optional, overrides the component's
    images:
      - image: registry.example.com/acme/web:1.0  # required
        builtBy: self                             # optional, overrides the component's
        digest: sha256:…                          # optional. Pin the immutable content digest
        signedBy: our-ci                          # optional. The provenance signer to expect here,
                                                  # whatever that signer's own patterns say
    hosts:
      - name: api
        url: https://api.example.com            # required
        type: api                               # browser | api (default browser); tunes header checks
        auth:                                   # optional, authenticates the dast scan
          type: bearer                          #   bearer | header
          header: X-API-Key                     #   required with type: header
          tokenEnv: STAGING_API_TOKEN           #   the variable holding it, which
                                                #   $DRAUGR_TOKEN_ENVS must list; there is no
                                                #   field for the credential itself, because a
                                                #   descriptor is committed
    kubernetes:
      - cluster: prod-cluster                   # required, a name declared under clusters:
        namespaces: [team-a, team-a-jobs]       # optional, the namespaces this component owns
    cloud:
      - account: shop-prod                      # required, a name declared under accounts:
        regions: [us-central1]                  # optional, the regions this component's resources are in
    imports:
      - control: sast                           # required, the control its findings belong to
        file: reports/checkmarx.sarif           # required, a SARIF 2.1.0 file another tool wrote
    controls:              # optional per-component overrides (same shape as config.controls)
      images:
        enabled: true
Control resolution: a component-scoped control runs for a component when it is enabled
on the component, or (absent an override) enabled globally under config.controls.
Several repositories on one component is supported and worth knowing the shape of: Draugr plans
one job per repository and runs them concurrently, and paths in a finding are relative to the
repository it came from. Two repositories that share a path therefore produce findings that look
alike, so a finding records which repository it came from, that is part of what makes it a distinct
finding, and the report grows a Repository column when findings span more than one. The same
applies to repositories a fragment contributes from another project.
Who publishes it: builtBy says whether this team publishes the thing being scanned (self,
the default) or somebody else does (upstream). It may be declared on a repository, on an
image, or on the component, where it covers every target that does not say otherwise. Most
specific wins, the same rule controls: follows.
It decides what the report tells you to do, and nothing else. The finding keeps its severity and its band, is still counted, and still reaches the gate: a flaw in somebody else's software is exactly as dangerous, and what differs is who can end it.
Nobody can upgrade a library inside an image they do not build. The fix is a newer image, or a wait
for whoever publishes it, so for an upstream image the fix list groups every finding in it into
one action, take a newer image, instead of listing each library as something to upgrade.
The same holds for a repository, and licenses are where it is felt most. A denied license in the dependency tree of a repository you do not publish is not a license you chose and not one you can swap out. The answers are to stop using the component or to record an exception, and "change the code" is neither. It applies to every control for the same reason: the declaration is about who can change the thing, which does not vary by what found the problem.
It is declared, never detected. Nothing inside an image says who built it, and a git remote is not a statement of ownership, plenty of teams publish from a fork, and plenty consume from one.
self is the default because a descriptor written by hand describes what a team builds. One
written by a surveyor describes a running cluster, where most images come from somebody else, and
that is the case worth declaring.
Component-wide is the form to reach for when the whole component is somebody else's software, a
vendor console, an open-source service you run from source. Writing it on each target instead means
a repository or image added later silently defaults back to self.
- name: analytics-console
  builtBy: upstream            # everything here is the vendor's
  repositories:
    - url: https://github.com/vendor/console.git
    - url: https://github.com/acme/console-config.git
      builtBy: self            # …except this, which we do publish
  images:
    - image: ghcr.io/vendor/console:4.2
Cluster namespaces: namespaces narrows a cluster to the part the component owns; omit it and
the component declares the whole cluster. The cluster-wide checks, such as ClusterRoleBindings,
admission webhooks and the CNI, run only for a component that declares the whole cluster, so a
shared cluster's answer is filed once. A namespaced entry gets the checks about objects in its
namespaces. kube-bench runs checks written as cluster-wide kubectl queries and kube-bench-job
reads a node's own filesystem, which has no namespace, so neither can honor a scope and neither is
run against a component that sets namespaces. The alternative would be a report that
looks scoped and lists somebody else's namespaces against this component, so the scan is not
planned, and the report says so under Caveats, in a not-measured row naming the component,
the scanner and the namespaces it could not be narrowed to.
Nothing has to be turned off by hand. One component claims the cluster whole and gets the cluster-wide and node-level checks; each team's component claims its namespaces:
clusters:
  prod-cluster: {context: prod-eu-admin}
components:
  - name: platform               # the cluster, claimed whole
    kubernetes:
      - cluster: prod-cluster    # cluster-wide checks, kube-bench and kubeBenchJob run here
  - name: team-a
    kubernetes:
      - cluster: prod-cluster
        namespaces: [team-a]     # draugr-k8s-policies narrows to this
Risk classification (exposure, criticality), optional, and the two axes of risk
prioritization: exposure is how reachable the component is (likelihood), criticality is the business
impact if it fails. Both are fixed ladders whose meaning an organization can redefine (the levels
stay stable). They feed finding prioritization; a component may be left unclassified.
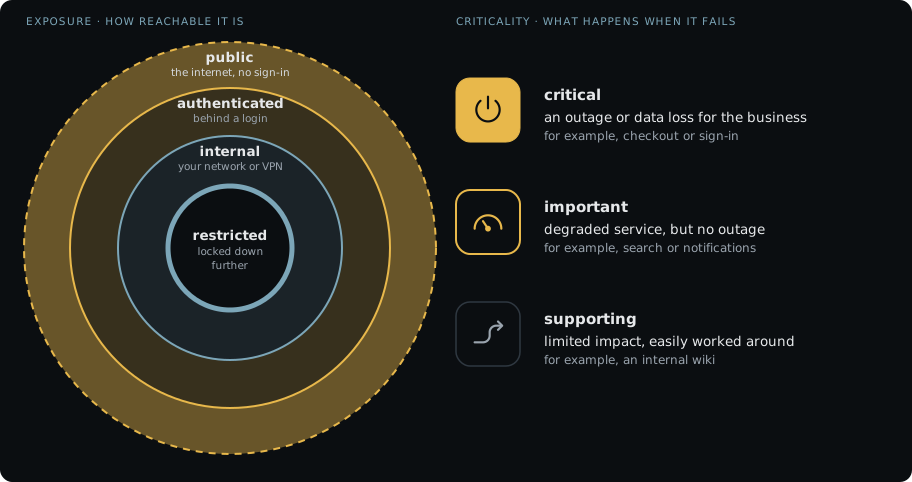
exposure | meaning | criticality | meaning | |
|---|---|---|---|---|
public | anyone on the internet, no sign-in | critical | an outage or data loss for the business | |
authenticated | on the internet, behind a login | important | degraded service, but no outage | |
internal | only from inside your network or VPN | supporting | limited impact, easily worked around | |
restricted | inside your network and locked down further, an allowlist, a private link, its own segment |
The wording names no platform on purpose: a Kubernetes network policy is one way to arrange
restricted, and Draugr classifies repositories and images as well as clusters. draugr classify
asks these same questions with the same words.
labels is free-form key: value metadata about a component, optional, and it is the
organization's vocabulary rather than Draugr's. Nothing here reads a key or attaches a meaning to
one, and no key is privileged: a team filing by squad, by regime, by data class or by all three is
describing its own shape, and a tool that decided what team meant would be describing a different
one.
components:
  - name: storefront
    labels:
      team: web
      data-class: pii
They never reach a verdict. What they do is answer whose, in the two places that question is
asked. draugr scan --labels team=web runs only what that team owns, which is how a pipeline in a
repository holding many teams' code stays about one of them. And every finding carries its
component's labels into results.sarif, while report.json lists the labels of every declared
component as componentLabels, including a component with no
findings. A platform expands a run from these two documents, so a fleet of many components can be
narrowed to the ones somebody is answerable for.
They are deliberately absent from the console, the Markdown report and a pull-request comment. Those answer what to fix, for a reader who already knows the work is theirs; filtering is a question asked where there is a fleet.
components[].imports
imports reads a SARIF 2.1.0 file another tool wrote into one of Draugr's controls, as though one of
that control's scanners had produced it. Its findings take this component's exposure and
criticality into their priority, count toward the gate, and appear in the fix list beside everything
Draugr found.
components:
  - name: api
    exposure: public
    criticality: critical
    imports:
      - control: sast
file: reports/checkmarx.sarif # relative to where Draugr runs| field | meaning |
|---|---|
control | the control the file's findings belong to, such as sast or sca |
file | the SARIF 2.1.0 file, relative to where Draugr runs |
Every finding in the file belongs to this component. Severity comes from each result's numeric
security-severity and otherwise from its SARIF level, and the report says which. The report
also names the tool and version the file states, when it was written, and its SHA-256, under
Measured against.
A file that states the commit it scanned is held to the commit this run reads, and a different
commit stops the run. A file that states none is read and listed under Caveats as unbound-imports,
which config.gate.failOnCaveats can make fail the run. A missing, unreadable or
invalid file stops the run as a scanner that could not run does. The
sarif-import page has the details, and Import another
scanner's SARIF walks through a pipeline.
config.controls
A map of control name → free-form settings. A control runs only when enabled:
controllers:is the older spelling. It still loads and is folded intocontrolswhen a descriptor is read, so nothing breaks;controlsis what to write, and what every other surface says.draugr controlslists them, the catalog names them, andconfig.gate.controlsused the word already. A controller is the Go type that plans the jobs.
config:
  controls:
    images:
      enabled: true          # absent entry ⇒ disabled; entry without `enabled` ⇒ enabled
A control name Draugr does not provide is an error, wherever it appears, here, in
config.gate.controls, or in a component's own controls. A typo is otherwise invisible: the
descriptor claims a decision it is not making, and the run goes green either way.
$ draugr validate draugr.saga.yaml
draugr: config.gate.controls: "iaac" is not a control this build of Draugr provides, did you mean "iac"?
Checked against what this build can run, which is also what draugr controls lists and what the JSON
Schema offers for autocompletion. All three
come from one place and cannot disagree.
Scanning an API from its specification
dast crawls an endpoint unless a host points it at an OpenAPI document. An API usually has no
HTML to crawl, so a specification is the difference between guessing and exercising what the
service declares.
hosts:
  - url: https://staging.example.com
    spec:
      path: ./openapi.yaml
      methods: [get, post]      # absent → GET and HEAD only
The declared URL wins over the document's servers: block. A scanner takes its targets from
the specification it is given, so a document naming production would send probe traffic there while
your descriptor said staging. Draugr rewrites servers: to your URL before the scan.
Read-only unless you name write methods. A specification lists DELETE too, and a scanner
handed one will use it. Every operation whose method is not named is removed from the copy the
scanner receives, so the restriction does not depend on the tool behaving. Naming post or delete
is how you accept it, per endpoint, and visible in review.
The run reports what it excluded, and how many operations declare parameters it could not supply, so a scan that covered part of an API does not read like one that covered all of it.
Paths resolve relative to where Draugr runs, like every other path in a descriptor.
Authenticating a dynamic scan
dast probes an endpoint anonymously unless a host says otherwise. Against an application that
requires a login that means it tests the login page, finds little, and passes, a verdict about the
least interesting part of the system.
hosts:
  - url: https://api.example.com
    auth:
      type: bearer
      tokenEnv: STAGING_API_TOKEN
export DRAUGR_TOKEN_ENVS=STAGING_API_TOKEN # set by the pipeline, beside the secret itselfEvery dast auth.tokenEnv must be listed in $DRAUGR_TOKEN_ENVS, because dast has no variable
of its own. An unlisted one fails the scan before the scanner starts, naming the variable.
type: bearer sends Authorization: Bearer <token>; type: header with header: X-API-Key sends
that header instead.
tokenEnv names a variable; there is no field for the credential. A descriptor is committed, so
a token in one is a leaked token. The value is read at the moment of the scan, written to a 0600
file for the scanner to read, and removed afterwards, never placed on a command line, where a
process list would show it, and never in a cache key or a report.
An unset variable fails the scan rather than falling back to anonymous, because a quiet fallback produces the pass this feature exists to prevent. The report records that the scan authenticated and which variable it read, so an authenticated run is never mistaken for an anonymous one, and the cache key carries the same marker, so adding credentials invalidates results gathered without them.
Per-scanner config
A control can be served by more than one scanner, and each scanner is configured under its own key
in controls.<control>.<scanner>. The key is camelCase, like every field in a Saga, so a
scanner whose name is hyphenated is configured under the camelCase form of it (kube-bench-job →
kubeBenchJob, draugr-tls → draugrTls). A hyphenated key is rejected at load: it would
otherwise match no scanner and quietly run one fewer than asked for. A scanner block holds an
optional enabled flag plus that scanner's options. Default scanners run unless turned off with
enabled: false; a non-default scanner runs only when it sets enabled: true. A component may
override the project config (component keys deep-merge over project keys). For sast:
config:
  controls:
    sast:
      enabled: true
      semgrep:
        config: p/owasp-top-ten   # ruleset: a registry ref or a path/URL (default: p/default)
      gosec:
        enabled: true             # opt-in scanner (Go-only), off unless enabled here
    threats:
      enabled: true
      virustotal:
        enabled: true             # opt-in: a second feed is a second party told about your hosts
        requestsPerMinute: 1000   # only if your key is a paid one; defaults to the free tier's 4
Every scanner declares the options it accepts, and anything else under its block is rejected before the scan runs, naming the key it could not honor. That includes the scanners that accept nothing: an option a scanner does not read is an error, not a setting that quietly does nothing.
A control declares its own settings too, so a key directly under a control is one of exactly
three things: enabled, a scanner's block, or a setting the control takes. Anything else is
rejected, whatever shape its value has.
enabled is true or false, under a control and under a scanner. yes, 1 and a quoted
"true" are rejected.
$ draugr validate draugr.saga.yaml
draugr: config.controls.sast: scanners are enabled under their own name, not in a list. Write `config.controls.sast.<scanner>.enabled: true` (it has gosec or semgrep)

run `draugr controls` to see what this build provides
The shapes that used to be accepted and do nothing: a list of scanner names, a scanner given a
value rather than a block (gosec: true enables nothing, because only a block is read), and a
misspelled setting. Each produced a descriptor that claimed a decision it was not making.
licenses takes settings of its own, deny and warn, and sca takes
devDependencies and
providedDependencies.
Which scanners take options, and which take only enabled:
| Scanner | Options |
|---|---|
mend-sca | productToken (required), project, resultTimeout, settings |
mend-licenses | the mend-sca options, plus deny and warn |
kube-bench-job | targets, benchmark, namespace, image, nodeSelector, timeout, context |
kube-bench | targets, benchmark, version, context, configDir |
trivy-license | deny, warn, SPDX identifiers; full, read LICENSE files and source headers too |
draugr-tls | expiryErrorDays, expiryWarnDays |
gosec | include, exclude, rule IDs; tags, Go build tags |
trivy, trivy-fs | pkgTypes (os, library), dbRepository, an internal mirror |
trivy-fs | filePatterns (analyzer:regex), which trivy-license reads the same repositories with; detectionPriority (precise, comprehensive); resolveMaven, fetch pom dependencies from Maven Central, declares disclosure; includeDevDeps, deprecated for devDependencies |
grype, grype-fs | byCve. Report under the CVE rather than the advisory ID, on by default |
trivy-config | checks, paths to your own Rego; namespaces, the top-level package names to evaluate, derived from the checks' package lines when unset |
semgrep | config, a registry ref, path or URL |
gitleaks | config, a rules file shared across repositories; history, scan commit history too, keeping findings whose path is inside the component's paths and ignore and reporting a secret still in the tree once, as the tree finding |
virustotal | requestsPerMinute |
nuclei, draugr-headers, draugr-k8s-policies, urlhaus, retirejs, cosign, notation | enabled only |
examples/scanner-options.saga.yaml writes every
option every scanner takes, with a line on what each one decides. It is a reference rather than a
starting point; copy the two or three lines you need.
Development dependencies
config.controls.sca.devDependencies decides whether a finding in a development dependency counts.
A development dependency is a package the manifest declares for development only, such as a test
runner, a build tool or a linter.
| Value | Each finding in a development dependency |
|---|---|
suppress, the default | Stays in the report and in report.json, suppressed with the reason development dependency, and out of the counts and the gate |
report | Is counted, with dev beside its package |
config:
  controls:
    sca:
      devDependencies: report       # count findings in development dependencies
components:
  - name: build-tools
    controls:
      sca:
        devDependencies: suppress   # replaces the project's setting for this component
Trivy reads development dependencies on every run and marks each one, in npm, Yarn, pnpm, Bun, uv
and Poetry lockfiles. Grype marks none, so a Grype finding takes the mark from Trivy's finding about
the same package in the same file. A Grype finding with no matching Trivy finding carries no mark and
is counted, including every Grype finding when trivyFs is off.
A pom.xml dependency in test scope is a development dependency too. Draugr reads the scope from
the pom in the checkout and marks every finding about that dependency in that pom. Trivy's pom
parser leaves test-scoped dependencies out, so their findings come from grypeFs.
The suppression's origin is setting and its source is the key that decided, so the report
lists it apart from config.exclude. A setting sets aside only the copy of a flaw it applies to. A
package that is a development dependency in one lockfile and a runtime one in another is counted
for the runtime copy.
trivyFs.includeDevDeps is deprecated. It is read for one release where devDependencies is
not written beside it, true as report and false as suppress, and draugr validate and
draugr scan print a warning naming the key to write.
Provided dependencies
config.controls.sca.providedDependencies decides whether a finding in a dependency the runtime
provides counts. A provided dependency is one a pom.xml declares in provided or system scope.
The application compiles against it and leaves it out of what it packages, and the server or
platform it is deployed into supplies the copy that runs.
| Value | Each finding in a provided dependency |
|---|---|
suppress, the default | Stays in the report and in report.json, suppressed with the reason provided by the runtime, and out of the counts and the gate |
report | Is counted, with provided beside its package |
config:
  controls:
    sca:
      providedDependencies: report       # count findings in provided dependencies
components:
  - name: batch
    controls:
      sca:
        providedDependencies: suppress   # replaces the project's setting for this component
Draugr reads the scope from the pom in the checkout and marks every finding about that dependency
in that pom, whichever scanner reported it. Trivy's pom parser leaves provided and system
dependencies out, so their findings come from grypeFs. A dependency with no scope of its own takes
the one the same pom's dependencyManagement gives it. A scope the pom leaves to a parent POM or an
imported BOM is not read, and the dependency is counted as one the application ships. An
<optional>true</optional> dependency is on the application's own classpath and is counted.
The suppression's origin is setting and its source is the key that decided, as for
development dependencies.
Reachability for Go
The sca control can also run govulncheck,
which asks a different question from the other scanners: not which dependencies have known
vulnerabilities, but which of those vulnerabilities this code can actually reach.
config:
  reachability:
    analyzers: [govulncheck]   # `draugr tools install govulncheck`; Go only, and needs a Go toolchain
  controls:
    sca:
      enabled: true
Beside config.exploitability, not in the sca scanner block, and the placement is the point.
Every entry in a scanner block adds findings, so enabling one there means check this too. An
analyzer named here adds none: it ranks findings already found, downward, which can turn a
failing gate green. That is a decision about how findings are ranked, the same kind
config.exploitability makes in the opposite direction, and it belongs where whoever owns the gate
will see it in a diff.
Naming an analyzer in a scanner block is rejected at load, with the line to write instead.
It adds no findings of its own. Its verdicts are folded onto the findings the manifest scanner
already produced, so a Go vulnerability is still reported once, not once as CVE-2022-32149 and
again as GO-2022-1059. A vulnerability only it reports is kept.
What a verdict does. A finding nothing can reach is ranked one severity level down when the analyzer says it followed calls or data to get there, and the report says why. A verdict reached any other way is reported and moves nothing; prioritization has the methods and what each one earns. The severity the scanner reported is unchanged either way: reachability feeds the priority matrix, exactly as exploitability enrichment does in the other direction, and where exploitability has already raised a finding that wins.
The report says what it decided, beside everything else that moved a ranking:
SIGNALS
  reachability  govulncheck · 2 reachable, 6 unreachable
and every finding whose band moved says so, the way an escalated one does:
  P2        medium    CVE-2020-14040  trivy  go.mod  golang.org/x/text v0.3.0 → v0.3.8
            ↓ unreachable · possibility to trigger an infinite loop · govulncheck, 2026-08-21
It never suppresses. An unreachable finding stays in the report at a lower band, because a
suppression records that a person decided and an inference is not a decision. A call graph does not
see reflection, dynamic dispatch or code generation, and the call that makes something reachable can
be written tomorrow. To excuse a finding, use config.exclude or a VEX
document, both of which carry an author.
Three verdicts, not two. reachable, unreachable, and unknown, and the third is what keeps
the other two honest. A dependency used only from test files produces no govulncheck output at
all, so the absence of a verdict is not evidence of unreachability. unreachable is only claimed
for a module the run actually analyzed; anything else is reported as unknown, and report.json
counts all three so you can see how much of the answer is missing.
The call path is in the SARIF and in report.json, ordered from your own code to the vulnerable
symbol. Go only, a reachability claim without its language is an overclaim.
Dependency health (config.dependencyHealth)
A CVE in a package whose publisher has walked away is a different problem from the same CVE in one that ships a fix next week, and no scanner reports the difference because it is not in the code.
config:
  dependencyHealth:
    enabled: true
Off unless you switch it on. Unlike the other two enrichments, which read a local cache somebody chose to fill, this one reaches deps.dev during the scan and sends it the list of packages the run found. Nothing else leaves the machine: no source, no findings, no descriptor.
Two statements move a finding, and both name who made them.
| Signal | What it means | What it does |
|---|---|---|
| Malicious | the package is in the OSSF Malicious Packages Project | ranks it critical |
| Deprecated | the publisher marked this version as no longer supported | raises its severity one level |
Everything else the service reports is read and deliberately ignored. A newer version existing is true of nearly every dependency, and a vulnerability it knows about is one your scanners already found, so acting on either would count one problem twice or rank on nothing.
Health scores never move a band. Not a simplification, a finding: reported vulnerability counts
rise with OpenSSF Scorecard's aggregate score rather than falling, at an R² of 9% to 12%, and
Scorecard's Maintained check scores PyYAML zero because it reads a 90-day activity window and
PyYAML is stable rather than abandoned. Ranking a CVE up because a maintainer commits rarely would
be wrong in a way the people who depend on that package would notice first.
It never gates on its own. A dependency choice is not a defect, and a build that failed because a maintainer walked away is one people learn to route around.
In the report, beside the other signals:
P1  critical  NSWG-ECO-328 · Cross-Site Scripting (XSS)
    ↑ deprecated · component web · scanner trivy · jquery 1.8.3 → >=3.0.0
    web/package-lock.json:10
The publisher's own words travel in report.json and the SARIF, where there is room for a sentence.
When the lookup answers, SIGNALS lists malicious and deprecated with the findings each raised,
or nothing raised. Neither row appears when the lookup did not answer.
SIGNALS
  KEV           2 findings listed · 2 raised
  EPSS          2 findings raised
  malicious     nothing raised
  deprecated    12 findings raised
  reachability  govulncheck · 2 reachable, 3 unreachable
report.json records the lookup under consulted.
What it covers. The language ecosystems deps.dev indexes: Cargo, Go, Maven, npm, NuGet, PyPI and RubyGems. Operating-system packages from a container image are not among them, so on an image-heavy project this speaks to the dependencies you chose rather than to the base you built on.
What it costs. One request per hundred packages, cached for an hour. The hour is the API's own
max-age, so it is a term rather than a setting, and it is why this signal has no offline path: a
run with no network reports that it could not consult the data and ranks without it.
CI (config.ci)
A run records who its CI system reports as having started the pipeline and who wrote the commit, as
a handle and the platform's stable id (see the report's ci block).
Email addresses are personal data, so they are recorded only when asked for:
config:
  ci:
    recordEmail: true
When off, no address is read. When on, a run records the addresses GitLab, Azure Pipelines and Buildkite report for those two people, and on GitHub the commit author's address from the push event. GitHub reports no address for whoever started the run.
Running two scanners on one control
A flaw both of them find is counted once. Both findings stay in the report. Each keeps its own rule id, severity and account, because the disagreement between two scanners is the reason to run two, but only one is counted in the verdict, the priority bands and the fix-first list, and the row you act on names the other tool:
P2  medium  4.3  CVE-2026-27205  sca  trivy  app/requirements.txt
    flask 0.12.2: Flask: Information disclosure via improper caching of session data
    also found by grype (low 2.3)
Where the scanners disagree about how bad it is, the stronger reading is the one counted and
the row says what the other said. Where they agree, the rating is not repeated. Every scanner's own
rule id, severity and score are in report.json and the SARIF either way.
Findings are matched on repository, package and vulnerability id, not on the rule id, because
scanners spell an advisory differently. Grype reports CVE-2020-14343-pyyaml where Trivy reports
the bare CVE, since one advisory can affect several packages in a scan.
An exclusion covers every scanner's copy. Excusing CVE-2020-14343 excuses it whichever tool
found it: a decision about a vulnerability is a decision about the vulnerability, not about one
tool's report of it.
draugr controls --options # the authoritative list, read from the same schemas the gate enforcesYour editor knows these too. The published schema names each control's scanners and the options each accepts, so completion and hover docs work inside a control block, and a scanner or option that does not exist is flagged as you type. It is generated from the same registry the gate consults, so the three answers cannot disagree.
No scanner option filters findings, and that is a rule rather than an omission. Trivy's
--severity and --ignorefile, gosec's -severity and -confidence, each drops findings inside
the tool, where Draugr never sees them. A finding Draugr never saw cannot be reported as suppressed,
cannot carry the reason someone gave for accepting it, and cannot be told apart from one that was
never made. Use config.exclude for a finding you have judged, which keeps it in
the report marked suppressed, and the gate thresholds for what should fail a build. Scanner options
decide what gets looked at; the gate decides what the answer means.
Paths in options, gitleaks.config, semgrep.config, trivyConfig.checks, resolve relative to where Draugr
runs, not to the repository being scanned. Repository scanners work in a temporary clone, and a
path resolving inside it would point at somewhere your file is not.
Scanners in the last row run with the arguments Draugr chooses. Where a control has more than one scanner, the choice you make is which one serves it, and that choice is the one that matters most, because it is what lets a descriptor outlive any particular tool.
Implemented today:
images(Trivy),sca(Trivy fs),licenses(Trivy),secrets(Gitleaks),sast(Semgrep; opt-in gosec),iac(Trivy config),kubernetes(native CIS checks; opt-in kube-bench),headers(native HTTP-header checks, including a graded CSP),dast(Nuclei),tls(native TLS/certificate probe), andthreats(abuse.ch URLhaus reputation. Needs a free key, and discloses your hostnames to a third party).sbomships as evidence underconfig.sbomrather than as a control.
draugr controlsis the authoritative list. It asks the same registry the validator and the JSON Schema do, so it cannot be out of date with the binary you are running. This one is prose, and prose drifts.
config.publishers
Declare where a run's results go, and what each destination is given. A publisher is a destination (a Publisher); a report is one rendered format (a Reporter).
config:
  publishers:
    - kind: file           # the artifacts, complete
      dir: ./out           # → ./out/results.sarif, ./out/report.html
      reports:
        - format: sarif    # any scan --format: console, markdown, html, junit, json, sarif
        - format: html
    - kind: github-pr-comment
      reports:
        - format: markdown
          minPriority: P2  # narrow the comment, not the artifact on disk
A destination that can deliver only one thing renders it for itself:
config:
  publishers:
    - kind: github         # complete. The SARIF is not a choice anybody makes.
    - kind: draugr-api     # the same: the run report and the evidence are its business
reports narrows those, and is required for file, which has no format of its own. Each distinct
report is rendered once, however many destinations ask for it.
Publisher fields
A field not listed for a publisher is refused, by draugr validate and by the schema. reports may
name only the formats in the last column.
| publisher | fields | reports |
|---|---|---|
azure-pr-comment | org, project, repo, pr, marker, tokenEnv | markdown, template |
azure-work-item | org, project, tokenEnv, label, branches, select, split, minPriority, children, maxChildren, labelBy, item | none |
draugr-api | url, tokenEnv | json, sarif |
file | dir (required) | any format, one or more required |
github | repo, commit, ref, tokenEnv | sarif |
github-issue | repo, tokenEnv, label, branches, select, split, minPriority, children, maxChildren, labelBy, item | none |
github-pr-comment | repo, pr, marker, tokenEnv | markdown, template |
gitlab-issue | repo, tokenEnv, label, branches, select, split, minPriority, children, maxChildren, labelBy, item | none |
gitlab-mr-comment | repo, pr, marker, tokenEnv | markdown, template |
tokenEnv names the environment variable holding the publisher's token, in place of the kind's
own: $GITHUB_TOKEN for the github kinds, $GITLAB_TOKEN for the gitlab kinds,
$SYSTEM_ACCESSTOKEN for the azure kinds and $DRAUGR_API_TOKEN for draugr-api. Any other name
must be listed in $DRAUGR_TOKEN_ENVS, comma-separated and set by the pipeline, or the publisher
fails before it sends anything. The environment reference says why the
pipeline decides.
For local artifacts and no destination at all, -o <dir> writes report.json and results.sarif.
--report <format> writes the formats it names instead of those two.
The template format renders a Go text/template against a
stable view of the scan, .Release, .Verdict, .Pass, .Priorities.{P1..P4}, .Controls, and
.Findings (each with .Priority .Level .Score .Control .Tool .RuleID .Message .Location). Use it
for a bespoke summary line, a Slack payload, or any custom text without writing code.
Reports are delivered regardless of the gate verdict, so you get evidence on a FAIL too. This is
independent of scan --format (stdout) and scan -o (which always writes report.json +
results.sarif). Use config.publishers when you want a declarative, multi-format,
multi-destination setup in the Saga itself.
Built-in publishers: file and github (uploads the sarif report to code scanning):
config:
  publishers:
    - kind: github         # repo/commit/ref default to the GitHub Actions env
      # repo: owner/name   # optional overrides ($GITHUB_REPOSITORY / $GITHUB_SHA / $GITHUB_REF)
      # ref: refs/heads/main
      # tokenEnv: GITHUB_TOKEN   # the token is read from this env var, never the Saga
minPriority narrows one report to findings at or above a priority band (P1–P4), leaving
every other report complete. It exists for the SARIF that becomes review comments: a reviewer shown
every finding in the repository reads none of them, while the JSON beside it is evidence and
evidence is not something to trim.
Narrowing an artifact is otherwise refused, and for a good reason, a file that claims to be the scan
and is not misleads whatever reads it, most sharply draugr diff, which reads a missing finding as
a fixed one. What makes this different is that it is declared: written in the descriptor, and
recorded inside the artifact it produced, so a consumer can tell a narrowed file from a whole one.
--min-priority on the command line still trims only what is printed; --artifact-min-priority is
the flag that narrows a file, and it says so in the file.
The github publisher renders the sarif report for itself, so kind: github is the whole of
it. It never stores a secret in
the descriptor. The token comes from an environment variable. Code scanning is free for public
repos; private repos need GitHub Advanced Security.
The github-pr-comment publisher posts the markdown report as a sticky pull-request
comment (updated in place on each push). It renders the markdown report for itself; repo
and the PR number default from the GitHub Actions environment; the token comes from $GITHUB_TOKEN
(or tokenEnv). It no-ops off a pull request. It's most useful with
draugr diff --publish, which posts a PR security
delta (new / fixed findings) as that comment.
The azure-pr-comment publisher is its Azure DevOps counterpart, with the same sticky behavior.
org, project, repo and the PR number default from the Azure Pipelines environment, so kind: azure-pr-comment on its own is usually the whole configuration. The token comes from
$SYSTEM_ACCESSTOKEN (or tokenEnv), which a pipeline must map into the step explicitly. See
reports & publishers for that and for the
repository permission the build identity needs.
org is the collection URL every request is sent to, with the token. It is used where its
origin is that of $SYSTEM_TEAMFOUNDATIONCOLLECTIONURI, or Azure DevOps Services
(https://dev.azure.com, https://<organization>.visualstudio.com). Any other origin is refused
before anything is sent. For Azure DevOps Server outside Azure Pipelines, set
$SYSTEM_TEAMFOUNDATIONCOLLECTIONURI to the collection's URL.
The gitlab-mr-comment publisher is the GitLab counterpart, with the same sticky behavior. The
project and the merge-request IID default from the GitLab CI environment, so kind: gitlab-mr-comment on its own is usually the whole configuration; repo accepts a numeric project
id or a full path, groups included. The token comes from $GITLAB_TOKEN (or tokenEnv) and must
carry api scope. CI_JOB_TOKEN is read-only on the notes API and cannot post, which is worth
knowing before reaching for the variable GitLab already provides. See reports &
publishers.
The github-issue publisher keeps a GitHub issue open while the gate fails. A run on a tracked
branch opens the issue, rewrites its body when the findings change, and closes it with a comment
when the gate passes. A pull-request run changes nothing. The body lists the actions that clear the
findings and the findings under each. See reports &
publishers for the lifecycle.
config:
  publishers:
    - kind: github-issue
      select:                        # the whole run when unset
        labels: { team: payments }
      split: component               # none (default) | control | component
      minPriority: P2
      children: actions              # none (default) | actions | controls
      maxChildren: 20                # 100 when unset
      label: draugr                  # the default
      labelBy: [priority, control]   # [priority] when unset; [] keeps none
      branches: [main, "release/*"]  # the default branch when unset
      item:
        labels: [triage]
        assignees: [octocat]
        milestone: Q4 hardening
type: Bug| Field | Default | Meaning |
|---|---|---|
select | the whole run | the findings and errors this entry's issues cover. components, labels and controls mean what --components, --labels and --controls mean. A list matches any of its values, every label must match, and the keys together must all match. |
split | none | control or component: one issue per control or per component within what select covers. An issue closes when its own part passes. |
minPriority | every band | P1 to P4. An issue opens only while it holds a failing finding at or above this band, and its body lists only those. The body's count of failing findings stays complete. |
children | none | actions or controls: each issue becomes a parent with a child per action, or per control holding that control's actions. controls is refused with split: control. |
maxChildren | 100 | 1 to 100. The most children open under one parent; the actions without one are listed in the parent. Set only with children. |
label | draugr | the label that finds this entry's issues, applied to each. Created when it does not exist. A comma is refused, and on Azure DevOps a semicolon. |
labelBy | [priority] | the facts kept on each issue as labels, from priority, control, exposure, criticality and incomplete. [] keeps none. |
branches | the default branch | branch names or globs, * matching any characters. A run on any other branch changes nothing. |
item.labels | none | labels applied beside label when an issue is created. A later run adds back one that was removed. |
item.assignees | none | logins on GitHub, or usernames of project members on GitLab, assigned when an issue is created. |
item.milestone | none | a milestone's title, open or closed, set when an issue is created. |
item.type | none | set when an issue is created: on GitHub an issue type the organization defines, on GitLab issue, incident or task, where incident needs the Reporter role and task is refused with children, and on Azure DevOps a work item type, the Task category's default when unset, or the Requirement category's for a parent. A child takes no type on GitHub, is a task on GitLab and the Task category's default on Azure DevOps. |
item.confidential | true | whether a new issue is visible only to project members. gitlab-issue only. |
item.tags | none | tags applied beside label when a work item is created. A later run adds back one that was removed. azure-work-item only. |
item.assignedTo | none | an email address, or a display name the organization resolves to one person. azure-work-item only. |
item.areaPath, item.iterationPath | the project's defaults | where a new work item is placed, as in Payments\Platform. azure-work-item only. |
item.priority | the process default | 1 to 4. azure-work-item only. |
item.fields | none | other fields set on a new work item, by reference name, and never on a child. A field the publisher writes, or one another item key sets, is refused. azure-work-item only. |
Each fact in labelBy is a label named draugr:<fact>:<value>:
| Fact | Label | On the issue while |
|---|---|---|
priority | draugr:priority:P1 | the band is the highest among the findings the issue lists |
control | draugr:control:sca | the issue lists a finding of the control |
exposure | draugr:exposure:public | the issue lists a finding on a component declaring the exposure |
criticality | draugr:criticality:critical | the issue lists a finding on a component declaring the criticality |
incomplete | draugr:incomplete | a scan error stops a control the issue covers |
Every run adds the fact labels that apply and removes the ones that no longer do, writing only when
they change, so a fact label removed by hand comes back and one added by hand is removed. A label
or item.labels value named like a fact label is refused.
The title names what tells an issue apart, then the project: the split part, the select, and the
run's --components, --labels or --controls, as in sca fails the Draugr gate · team=payments · shop. An issue with none of them is shop fails the Draugr gate.
With children, a child's title is its priority, then the action's title or the control's name, as
in P1 · Upgrade jinja2 2.10, and its body is the action's findings or the control's actions. The
parent opens with how many actions have a child, then lists the actions that have none. Children are
created highest priority first, up to maxChildren open under one parent and within the run's wait
budget; the next run
creates the rest. A child closes when the run no longer reports its action or control, when the
parent's part passes, or when children changes. A child is a sub-issue on GitHub, which needs
GitHub.com or GitHub Enterprise Server 3.18 or later, a task given its parent through the GraphQL
API on GitLab, and a child work item on Azure DevOps.
After an issue is created it belongs to whoever triages it: a reassignment, a moved milestone or an
edited title survives the next run, and a child's edited title survives until its priority changes. Each issue carries a hidden marker naming the project, the run's
scope, select and the split part, and a run acts only on the issues whose marker matches it, so a
run narrowed with --controls never closes an issue a full run opened. The descriptor must set
project.
In GitHub Actions the repository and $GITHUB_TOKEN (or tokenEnv) come from the environment, and
the workflow grants permissions: issues: write. A fine-grained token needs Issues: write. Without
push access GitHub drops labels, assignees, milestone and type from a new issue without an error,
so the publisher compares the created issue with the request and fails naming what was dropped.
With push access GitHub refuses a value it cannot apply, such as a login that cannot be assigned,
and the publish fails naming it.
An issue on a public repository is readable by anyone, and the body lists findings with their
files and lines. Listing the same repository's code-scanning alerts takes write access. For a public
repository, upload findings to code scanning with the github publisher instead.
The gitlab-issue publisher keeps a GitLab issue open on the same terms and reads the same
fields. The project and the API root come from the GitLab CI environment, and repo accepts a
numeric project id or a full path. The token comes from $GITLAB_TOKEN (or tokenEnv): a
fine-grained token with Work Item: Create, Read and Update, Label: Read and Member: Read, or
one with the api scope, of a user with the Planner role or higher. CI_JOB_TOKEN cannot write
issues. A new issue is confidential unless item.confidential is false. GitLab records no close
reason, so the comment posted before the close is the only record of why. GitLab Free keeps one
assignee, and the publish fails naming any assignee GitLab dropped.
config:
  publishers:
    - kind: gitlab-issue
      item:
        assignees: [alex]      # a project member's username
        type: incident         # issue (default) | incident | task
        confidential: false    # true when unset
The azure-work-item publisher keeps an Azure Boards work item open on the same terms and
reads the same fields, with Azure's in item in place of labels, assignees and milestone. org and
project default from the Azure Pipelines environment, and org is held to the rule above. The token comes from $SYSTEM_ACCESSTOKEN
(or tokenEnv), mapped into the step; the build identity needs View and Edit work items in this
node on the area path, and Create tag definition for a tag new to the organization. The
description is Markdown; Azure DevOps Services is supported, and Server is untested. A work item
closes to the state in the Completed category of its type, after a comment saying why. Azure
Pipelines names no default branch, so unless branches is set the publisher reads it from the
repository, which needs Read on it. See reports &
publishers.
config:
  publishers:
    - kind: azure-work-item
      item:
        tags: [security]
        assignedTo: alex@example.com
        areaPath: Payments\Platform
        priority: 1                     # 1 to 4
        type: Bug                       # the Task category's default when unset
        fields:
          Custom.Team: Payments
When an entry sets select, draugr doctor lists the components no issue entry covers under
UNTRACKED.
The draugr-api publisher posts the run to any server implementing Draugr's run-ingest API.
Draugr Server is one, hosted, or installed where you want it, the same
artifact either way, and the calls are documented in reports &
publishers so anything else can be another.
config:
  publishers:
    - kind: draugr-api
      # url: https://draugr.acme.example   # only on $DRAUGR_API_URL's origin, or one
      #                                    # $DRAUGR_API_ORIGINS lists
It renders the run report and its evidence for itself. The token comes from $DRAUGR_API_TOKEN (or
tokenEnv) and never from the descriptor, which is a file people commit.
A server that judges an organization's policy is also asked about the descriptor before the scan starts, with the same endpoint and token, and its verdict can refuse the run or fail its gate. See the organization's policy.
The environment chooses the server. The token goes to the first of:
$DRAUGR_API_URL.publish.apiUrlin~/.draugr/config.yaml, or in the file--configor$DRAUGR_CONFIGnames.
url: is used only on that server's origin, or one $DRAUGR_API_ORIGINS
lists (comma-separated). A url: on any other origin fails the scan before any scanner runs,
naming the two values that disagree. With a token set and no $DRAUGR_API_URL, a url: the list
does not name is refused the same way, and the error names $DRAUGR_API_URL. publish.apiUrl in
the ./draugr.config.yaml beside the descriptor is held to the same rule, and is ignored while
$DRAUGR_API_URL is set or the descriptor has a url:.
In practice, put the endpoint in the runner's ~/.draugr/config.yaml or $DRAUGR_API_URL, and
write url: in a descriptor only to choose a path on that server, or a second server the pipeline
lists in $DRAUGR_API_ORIGINS.
report.json travels in the request; results.sarif does not travel through the API at all.
The server answers with a URL and the publisher uploads the evidence directly to storage. At roughly
2.5 KB of SARIF per finding, a descriptor covering twenty images is around 20 MB before anything
unusual happens, and a request body is the wrong place for it.
Two things follow that are worth knowing when reading a build log:
- A re-run that produced the same findings uploads nothing. The server addresses evidence by its content, so it can say it already holds it.
- A retried job does not become a second run. The run is keyed on the CI job id where the platform provides one, GitHub Actions, GitLab CI, Azure Pipelines, CircleCI and Buildkite, and on the digest of the report where nothing does.
With neither the URL nor the token set, the publisher skips, so the same descriptor a pipeline uses still runs on a developer's machine. Setting one without the other is an error: a scan that silently did not publish is one somebody believes was published.
Provenance signers (controls.provenance)
config:
  controls:
    provenance:
      enabled: true
      unmatched: observe          # observe (default) | warn | fail
      trustRoot: .draugr/sigstore-root.json   # optional, for a runner with no egress
      signers:
        - name: our-ci            # required. How an image's signedBy refers to it
          images: ["ghcr.io/acme/*"]          # what this signer covers; * spans any characters
          github:                             # a GitHub Actions signer, written as its parts
            repository: acme/ci-workflows
            workflow: .github/workflows/build-image.yml
            ref: refs/tags/v3
        - name: chainguard
          images: ["cgr.dev/chainguard/*"]
          keyless:                            # the general form, one field per cosign flag
            issuer: https://token.actions.githubusercontent.com
            identityRegexp: ^https://github\.com/chainguard-images/images/.*$
        - name: acme-pki
          images: ["acme.azurecr.io/*"]
          x509:                               # a Notary Project signature, checked with notation
            trustStore: .draugr/truststore/acme-ca.pem
            subject: "C=US, ST=WA, O=Acme, CN=Acme Release Signing"
Checks that each image is signed by the identity declared for it.
A signer declares exactly one of keyless, github and x509, because a signature is checked one
way. keyless takes an issuer and one of identity or identityRegexp; github takes the three
parts and expands to the same thing, which draugr validate prints; x509 takes a PEM file of
root certificates and the subject the signing certificate must carry.
Which verifier runs follows from that. keyless and github go to cosign, x509 goes to
notation, and an image no signer covers goes to cosign, which is the only one that can read
back a signer nobody named. A project signing some images with Sigstore and others with a
certificate declares both kinds and needs no flag.
An identity is not optional. A signer with none would accept a signature from anybody, which is the failure this control exists to catch, and it is refused rather than treated as a default.
Which signer covers an image: the one its signedBy names, or the one whose images patterns
match. Two signers matching one image is refused; narrow the patterns, or name one with signedBy.
An image no signer covers is observed, and unmatched decides what that absence is worth.
A component's signers are added to the project's rather than replacing them, the same way the license policy is unioned. A component that replaced the list could stop checking most of what it runs while still reading as a policy.
builtBy is not consulted here. draugr survey records images with no builtBy, which resolves
to self, so keying on it would expect the organization's own signer on every sidecar in a
surveyed namespace.
See the how-to for finding the identity your builds already sign with.
License policy (controls.licenses)
config:
  controls:
    licenses:
      enabled: true
      deny: ["AGPL-3.0-only", "GPL-3.0-only"]   # → error, whatever category Trivy assigned
      warn: ["MPL-2.0"]                          # → warning

components:
  - name: shipped-cli          # distributed to customers, so stricter
    controls:
      licenses:
        deny: ["LGPL-3.0-only"]
Reports dependency licenses that carry an obligation. Requires Trivy.
Not legal advice. License interpretation depends on facts Draugr can't know, whether you distribute, how you link, which jurisdiction applies. Findings are a starting point for a conversation, not a determination. See scope and disclaimer.
It reports problems, not inventory. By default the level follows Trivy's own classification:
| Trivy category | Level | |
|---|---|---|
forbidden | error | generally incompatible with shipping proprietary software |
restricted | warning | copyleft, GPL, LGPL |
reciprocal | note | file-level copyleft, MPL, EPL |
unknown | note | Trivy couldn't identify it |
notice, permissive, unencumbered | not reported |
Permissive licenses aren't findings, they're inventory. Every dependency has one, and listing them
buries the few that matter under dozens that don't. On Draugr's own repository that's 77 licenses,
of which zero carry an obligation. The inventory question is what config.sbom
answers, with a license per package.
restricted is a warning rather than an error because whether copyleft matters depends on
whether you distribute, which the Saga doesn't say. If you ship binaries to customers, raise it:
deny: ["GPL-3.0-only"].
deny and warn name SPDX ids and beat the category, because whether a license is acceptable
depends on what you do with your software. Trivy can't know that; you always do.
Gate it separately from vulnerabilities with config.gate. License policy is
usually owned by different people than security policy:
config:
  gate:
    failOn: high           # this descriptor gates on severity…
    controls:
      licenses: error      # …and a denied license fails the build on its own threshold
How project and component settings combine
This differs from every other controller, deliberately, and it's the one thing worth reading twice.
Elsewhere, a component's block deep-merges over the project's and the component wins, so a
component setting a list replaces the project's list. For deny and warn, the two union
instead. A component can add restrictions; it cannot remove them:
config:
  controls:
    licenses:
      deny: ["GPL-3.0-only", "AGPL-3.0-only"]   # the organization's policy

components:
  - name: web
    controls:
      licenses:
        deny: ["Sleepycat"]      # web denies all three, not just Sleepycat
Under the usual rule, web would have silently dropped both organization-wide denials, a component
opting out of company license policy, invisible in review. That's the failure a license gate exists
to prevent, so components can only tighten.
There is exactly one way to loosen, and it requires a reason:
config:
  exclude:
    - rules: ["license/GPL-2.0-only/*"]
      reason: "Legal reviewed 2026-07; we link dynamically and don't distribute."
Which is the point. An exemption you have to justify, that stays in the report marked and auditable, is a different thing from a list entry nobody has to explain.
Rule ids
license/<spdx-id>/<package>, e.g. license/GPL-3.0-only/github.com/somelib/thing. License
first so the common exemption is license/GPL-3.0-only/*; the full id when you mean one
dependency. Package names contain slashes, which is why rules patterns match * across
separators.
Findings resolve onto the line where the dependency is declared, so they land on the right row in
your editor. go.mod and requirements.txt resolve cleanly; nested lockfiles may not, and a
finding whose line can't be determined still points at the file.
config.allowEffects
Scanner effects this project accepts. A scanner that does more to a target than read it declares
an effect; the kinds that require consent (mutate, privilege) will not run unless listed here.
| Kind | |
|---|---|
mutate | creates or changes something that outlives the scan. needs consent |
privilege | needs access beyond what reading the target requires. needs consent |
network | sends traffic to the target rather than reading an artifact |
disclosure | sends information about the target to a third party |
network and disclosure are recorded but not gated. The controls that do them exist to do
them, and a prompt for the thing the control is for becomes a keystroke people learn to skip.
Both carry an obligation stated rather than enforced: that you are entitled to probe the host, and
that you are content for the third party to know what was sent. What was sent is in the effect's
detail line, because "a hostname" and "your source code" are not the same decision.
config:
  allowEffects: [mutate]
In the descriptor rather than only a flag because it is a decision about what may be done to your
systems: reviewed in a pull request, and applied identically by every pipeline instead of
remembered by whoever wrote the workflow. --allow-effects does the same for a single run.
config.gate
config:
  gate:
    controls:
      licenses: P2         # this control fails on a P2…
      sast: P4             # …this one fails on anything at all
controls refines the gate, in the gate's own vocabulary. A descriptor that writes no failOn
still has one, the default P1, so the thresholds above are bands. Writing a severity under a band
gate is refused rather than compared against something it does not measure:
draugr: config.gate.controls["licenses"] is "high" and the gate it refines is the band P1, which
asks the other question. Write `failOn: high` to judge this run on severity, or write these
thresholds as bands (P1, P2, P3, P4)
The severity form is the same shape with failOn written out:
config:
  gate:
    failOn: high           # gate on severity rather than on the band
    controls:
      licenses: critical   # this control fails only on a critical…
      sast: low            # …this one fails on anything at all
Severity values are critical, high, medium, low. The SARIF levels error, warning and
note are still accepted and mean high, medium and low.
One threshold can't serve every control. License policy is owned by legal and vulnerability policy by security; "fail the build on a forbidden license but only warn on a medium CVE" is a reasonable position that a single global threshold makes unsayable.
failOn takes either vocabulary. A priority band (P1–P4) asks
what band a finding landed in for the component it was found in; a severity (critical, high,
medium, low) asks what the scanner called the flaw on its own terms. One field, because two
made it possible to write both, and a verdict with two possible reasons cannot be read back to the
rule that produced it. Empty is the default, which is P1.
--fail-on overrides it for a single run. failOnPriority is
the older spelling of the band and still works.
Both live in the Saga rather than in a flag because they're policy, reviewed in a pull request
and applied identically by every pipeline, not remembered by whoever wrote the workflow. Resolution
order is per-control setting → --fail-on → high.
The report says which gate produced a verdict, so a narrowed one is visible to whoever reads it. See the verdict and the gate.
failOnCaveats lists the kinds of caveat that fail the run as an error does. A caveat is a shortfall
in what the run covered, listed under Caveats in the report:
| kind | means |
|---|---|
not-checked | a part of the component the run did not examine: a surface it declares that no enabled control looks at, or, on a scan with no descriptor, a file whose scanner could not run on this machine |
not-measured | a scanner that cannot honor a component's scope, so it did not run for that component |
unread-files | a file whose contents no scanner read in full, in a repository that was read: a dependency file, a Terraform file calling a module that was not loaded or not evaluated, a Helm chart that was not rendered, a file the secrets scan skipped, a source file Semgrep skipped or did not finish, or a go.mod gosec found no Go package in |
unread-checks | a cloud check the scan could not evaluate, because a read it needs was denied |
unbound-imports | an imported SARIF file that names no commit, so nothing ties its findings to the code being scanned |
config:
  gate:
    failOnCaveats: [unread-checks]   # a denied cloud read fails the run
A caveat of a listed kind stays under Caveats, marked ✗, and the heading says how many fail the
run and under which setting. Its component reads ERROR, the scan exits non-zero as an incomplete
one does, and --allow-scan-errors accepts it. Empty, the default, fails on none, because a caveat
often follows from a choice: a descriptor narrowed on purpose declares surfaces no control looks at.
--fail-on-caveats overrides the list for one run, and
draugr doctor fails before the scan when the list names
not-checked.
failOnNew is the threshold at which a new finding fails the build. A finding is new when this scan
reports it and the base scan it is compared against does not. It takes the vocabulary failOn
takes, a band or a severity, and asks its question of the new findings alone, so the two can name
different thresholds and different vocabularies.
config:
  gate:
    failOn: P1             # a scan of the whole tree fails on a P1…
    failOnNew: P2          # …and a change fails on a new P2
draugr scan --base and
draugr diff apply it, and their --fail-on-new overrides
it for one run. A scan given a --base is then judged on its change alone: failOnNew gives the
verdict and the exit code, and the outcome of failOn over the whole run is recorded and decides
nothing. A scan with no --base has nothing to compare against, so failOn judges it and the report
states the setting with no comparison. Empty, the default, applies no gate to new findings.
config.fixes
config:
  fixes:
    upgrade: minor          # patch, minor, or major (the default)

components:
  - name: billing
    fixes:
      upgrade: patch        # overrides config.fixes for this component's findings
upgrade is the largest version step the fix list proposes for
a dependency. An upgrade the policy covers stays one action. Where some of a package's findings
need a larger step, the package gets two actions: the upgrade within the policy, banded by the
findings it clears, and the step past it, banded by the findings only it clears and labeled with
its size and the policy. On draugr-demo with upgrade: minor:
  P2  Upgrade jquery 1.8.3 → 1.12.0
      component api · control sca · 3 findings · app/static/js/jquery.min.js vendored · CVE-2012-6708 +2
  P1  Upgrade jquery 1.12.0 → 3.5.0  major · beyond policy minor
      component api · control sca · 4 findings · app/static/js/jquery.min.js vendored · CVE-2020-11023 +3
A package's two actions are listed together, ranked by the worse band of the two.
| Value | The largest step proposed |
|---|---|
patch | keeps the major and minor version, 1.4.2 to 1.4.9 |
minor | keeps the major version, 1.4.2 to 1.9.0. Below 1.0, a minor step counts as major, as npm's and Cargo's caret ranges treat it, so 0.3.0 to 0.4.0 is past minor |
major | any, the lowest release that clears every finding |
The policy changes what is recommended, never the verdict: the gate counts every finding whichever action it lands in.
It applies where versions are semantic. A distribution's packages (Debian, Alpine, Red Hat), a
calendar version, and a Maven version with a qualifier such as 31.1-jre are not split, and
report.json marks their actions policyApplies: false. The fix list counts them once, under its
heading, by ecosystem. On python:3.8-slim scanned as an image the team builds:
policy minor · not applied to 4 actions · debian 4A component's fixes replaces the project's, and fixes has no effect on an action that is not
an upgrade.
Where a repository comes from: URLs and paths
url accepts either a remote URL or a local path. The field is named for the common case;
anything git can clone is valid.
repositories:
  - url: https://github.com/acme/web.git   # remote, cloned over the network
  - url: git@github.com:acme/web.git       # remote, uses your SSH agent
  - url: ../web                            # local, relative to where Draugr runs
  - url: /srv/checkouts/web                # local, absolute
A relative path resolves against where Draugr runs, like every other path in a descriptor, so
run it from the directory the descriptor's paths were written for. In CI that is the GitHub
Action's working-directory input or a pipeline step's working directory. draugr scan <dir> with
no descriptor synthesizes one whose url is that directory's path from where Draugr runs: . for
the working directory, a relative path for a directory beneath it, and the absolute path for any
other.
A directory inside a checkout is scanned as part of that checkout. Draugr clones whole
repositories, so url: services/payments, or the url: . that draugr init writes in a
subdirectory, clones the checkout's root and scans the directory as though
paths had named it. paths and ignore written beside such a url stay
relative to the directory, but findings name files from the repository root. A directory that no
repository holds fails as not a git repository, even with --working-tree.
Both kinds are cloned. A local path is not read in place: Draugr clones it into a temporary
directory the same way it clones a URL, applies paths and ignore as
a sparse checkout, and runs the scanners over that. Three things follow, and they are the reason
this section exists.
The scan sees the committed revision, not your working tree. Uncommitted work, edited, staged, or untracked, is simply absent. A change that introduces a finding passes until it is committed, and a fix appears not to have worked. This is deliberate: a report has to name a revision that someone else can check out and reproduce, and "whatever was on one machine at one moment" is not that.
So the report names it, along with what it left out:
Scanned: https://github.com/acme/web at 3f9a1c2b (3 uncommitted files not included)A repository is named by the repository, not by how you reached it. Three details follow, and all three exist so that one repository reads as one thing however it was scanned.
A local checkout is reported as the repository it was cloned from. Point a descriptor at . or
/srv/web and the report names its git remote, because the path is where the code sits on one
machine rather than which repository it is. That is what lets a scan on a laptop and a scan in a
pipeline recognize each other: same repository, same revision, same identity, so they share a cache
entry, and draugr diff can compare them. A checkout with no remote keeps its path, which is
then the only name it has and the one you can act on.
Credentials and usernames are dropped. https://oauth2:TOKEN@github.com/acme/web.git is reported,
cached and named as https://github.com/acme/web, and Azure DevOps URLs stop carrying the
organization as a username as well as in the path. The URL used to clone keeps everything it
had. Fetching is the one thing credentials are for.
Every spelling is one name. A repository is reported as https://host/path, whichever way the
descriptor or the remote wrote it:
| written | reported as |
|---|---|
https://github.com/acme/web.git | https://github.com/acme/web |
git@github.com:acme/web.git | https://github.com/acme/web |
ssh://git@github.com:22/acme/web | https://github.com/acme/web |
git@ssh.dev.azure.com:v3/acme/platform/web | https://dev.azure.com/acme/platform/_git/web |
https://acme.visualstudio.com/platform/_git/web | https://dev.azure.com/acme/platform/_git/web |
The host is lowercased and the path is not, because some forges treat a path's case as meaningful.
A port stays where it is part of the address, https://ghe.internal:8443/…, and goes where it
belongs to SSH. A local path with no remote, and a file:// URL, are reported as written.
draugr diff compares by the same name, so a baseline from before this rule still matches a scan
made after it.
That line is in the console report, the Markdown and HTML ones, and the JSON under repositories.
It is per repository and per revision rather than per control: several controls scanning one
checkout is one fact. If two controls somehow read different commits, possible on a branch that
moves mid-scan, since each scanner checks out independently, both are listed, because a single
revision would be an assumption rather than a record.
For the loop of fixing something, draugr scan --working-tree reads the checkout as it is.
Uncommitted work included, from a copy, and marked in the report as not reproducible. See the CLI
reference.
revision still applies. A local path with revision: main scans main, whatever branch the
working copy happens to be on. Left unset, the scan follows the checkout's current HEAD, which is
usually what you want locally and worth pinning in CI.
The clone is a copy. Nothing a scanner does can modify your checkout, and the temporary directory is removed when the scan ends.
Use a local path for iterating on a descriptor, for scanning something not pushed anywhere, and for a monorepo where several components share one checkout. Use a URL in CI, where the path is the runner's and means nothing to anyone reading the report later.
What this means for draugr diff
diff compares two results.sarif files, so it inherits this: both sides describe committed
revisions. In CI that is exactly right. The base is a merge-base commit and the head is the PR's
head commit, both pushed, both reproducible, and it is why the GitHub
Action needs fetch-depth: 0 to reach the base.
Locally it is the part that surprises people. This does nothing:
draugr scan . -o base/
vim app/handler.py          # introduce something
draugr scan . -o head/
draugr diff base/results.sarif head/results.sarif   # → no change
Both scans cloned the same HEAD, so both SARIF files are identical. Commit between them, and
the diff is real:
draugr scan . -o base/
git commit -am "add the endpoint"
draugr scan . -o head/
draugr diff base/results.sarif head/results.sarif
Or scan two revisions explicitly by pointing revision at each in turn, which is closer to what
CI does and does not disturb your branch.
Scoping a repository
A monorepo holds more than one component, and a component is rarely the whole tree. paths and
ignore narrow what a scan looks at.
repositories:
  - url: https://github.com/acme/monorepo.git
    revision: main
    paths:
      - services/web        # only this subtree…
    ignore:
      - "**/testdata/**"    # …minus the fixtures inside it
      - vendor/
paths selects directories and files. services/web and services/web/** mean the same
subtree; a trailing /** is accepted because it reads naturally. go.mod means that one file.
Draugr checks out only what paths names, so a large repository is also cheaper to scan. The rest
is never fetched.
A file at the repository root is scanned only when paths names it. A root lockfile, go.mod
or Dockerfile belongs to the component that lists it, so two components sharing a repository do
not each report the findings in it. A component built from the root module or workspace names the
files it builds from:
paths: [services/web, go.mod, go.sum]A workspace member whose lockfile sits at the root and is not named appears under Caveats as
unread-files with no lockfile, so a missing entry shows in the report. The scanners' configuration at the root is
kept for every component whatever paths says: .trivyignore, .trivyignore.yaml, trivy.yaml,
.semgrepignore, .gitleaks.toml, .gitleaksignore and .grype.yaml.
An entry the repository does not hold is an error, naming the entry, at the revision being scanned.
ignore removes paths, and runs last, so it can carve out of a subtree paths selected. The
patterns are gitignore-shaped: a trailing / matches a directory and everything beneath it, *
matches within one path segment, ** matches across segments. A bare name like vendor means the
directory and its contents.
Both are relative to the repository root; an absolute path or one containing .. is rejected
when the descriptor loads.
Scope is part of a target's identity. Two components pointing at different subtrees of the same repository are two different scans, cached separately, and their findings stay apart.
History findings follow the same scope. Git history cannot be checked out by subtree, so
gitleaks with history: true walks every commit in the repository. Draugr keeps a history
finding only when the path it names would have been checked out, by the rules above. That path is
the one the secret had in the commit that introduced it, so the finding belongs to the component
whose paths held that path.
gosec and govulncheck
analyze whole Go modules. Both type-check packages, and a package does not type-check without the
packages it imports, so a component whose paths hold part of a module is analyzed with all of it.
The modules analyzed are the ones holding a .go file paths selects and the ones whose go.mod
it names. A path with no Go code in it, a frontend directory, adds none. Components carved out of
one module share one checkout. gosec analyzes it once; govulncheck analyzes it once per component,
starting from the packages that component's paths hold, so its verdict describes calls from that
component's own code. Each finding goes to:
- the component whose
pathshold the finding's file; - when no component's
pathshold it, every component whosepathsname the module'sgo.mod. Aninternal/package two services import and neither lists is the usual case.
A component's ignore still removes the findings in the paths it matches. A repository named by a
remote URL is analyzed as paths writes it, because its tree cannot be listed without fetching it.
ignorehere is not the same tool asconfig.exclude, below.ignorenarrows what is scanned, the files never reach the tool, and nothing is reported about them.excludenarrows what is counted: the finding is still made, still in the report, marked suppressed with the reason someone gave. Useignorefor code that is not yours to answer for, like a vendored tree. Useexcludefor a finding you have looked at and accepted.
config.exclude
config:
  exclude:
    - paths: ["test/integration/repo_scan_test.go"]
      rules: ["private-key"]
      reason: >-
        The integration test writes a throwaway key so the secrets control has something real
        to find. The material is fake and was never valid anywhere.

    # A risk accepted for now rather than forever.
    - rules: ["CVE-2026-12345"]
      reason: "Upstream fix lands in v2.4. Reachable only from the offline importer."
      expires: 2026-08-14
Every real repository has paths that aren't the application, fixtures, examples, generated code, vendored trees, and rules that don't apply to them. Saying so in the Saga means one syntax for every scanner, in the file that already describes your scope, rather than learning each tool's own ignore format.
How paths matches
Two rules, and which one applies is decided by the last character.
| Pattern | Rule | Matches |
|---|---|---|
ends in / | prefix | everything beneath that directory, at any depth |
| anything else | glob | one path, where * and ? stay inside a single segment |
* does not cross a /. tests* matches tests and testsuite.go, and matches nothing
inside tests/. To exclude a directory and everything under it, write the trailing slash:
paths: ["tests/"]        # the whole tree beneath tests/
paths: ["tests/*.go"]    # Go files directly in tests/, and no deeper
** is refused. It is not a syntax this field has, and left to the glob the second star reads
as another single-segment wildcard, so tests/** would quietly match one level down while looking
like it matched every level. draugr validate rejects it and names the trailing-slash form, which
already expresses the same thing.
draugr validate warns when a pattern names a directory that exists and does not select what is
in it, which is the shape that reads as written and applies to nothing:
✓ draugr.saga.yaml is valid
  ! config.exclude[0].paths[0] "tests*" matches inside one path segment, so it will not match
    anything under tests/. Write "tests/" to exclude the directory and everything beneath it
A warning rather than a failure, because a rule written ahead of the file it covers is legal, and the check is against whatever tree sits beside the descriptor. A descriptor whose repositories are all remote has nothing to check against and says nothing.
Two fields take path patterns and they do not match alike.
repositories[].ignore decides what is scanned and does cross
separators, so **/testdata/** is valid there. config.exclude[].paths decides what is counted
and does not. There is no pattern here for "every fixtures directory wherever it sits"; name each
one from the repository root, one per line.
A suppressed finding is reported, not deleted. It stays in the SARIF marked with its
justification (suppressions[].kind: external), so GitHub code scanning files it as
closed-as-suppressed and an auditor can see exactly what was set aside and why. It stops
counting: no summary, no verdict, no fix-first row. The console says how many:
ACCEPTED
  config.exclude  5 findings suppressed
That line is the point. An exclusion that left no trace would read exactly like a finding that was never there.
| Field | Meaning |
|---|---|
paths | Location patterns. A pattern ending in / matches everything beneath that directory; otherwise it's a glob against the whole location, so *.md and test/fixture.go both work. |
rules | Rule ids. * matches any run of characters, including /, so CVE-2019-* and license/GPL-3.0-only/* both work. A pattern with no * matches exactly. |
reason | Required. Why this exclusion exists. |
expires | The date it stops applying (YYYY-MM-DD). Past it the finding returns and the report says the exclusion lapsed. |
vex | What this suppression claims about the product, for --report vex. Optional. See below. |
Who, why, and until when. The question asked of a suppression is not whether the scanner ran. It
is who decided this was acceptable, and when. reason answers why and expires until when. Who is
answered by the repository's history of the exclusion's line, the last commit to change it, its
author and its date, which a reviewer reads with git blame and the report carries for each
exclusion.
--evidence prints each exclusion that set findings aside, with its file and line and git's record
of that line. From a scan of a descriptor and one fragment, each committed by a different author:
DECISIONS
  a fixture key, issued by nobody
  draugr.saga.yaml:15 · covers 1 finding · aws-access-token · no expiry
  last changed in 2a4674526bba by Ada Lovelace, 2026-09-14

  test fixtures, never deployed
  excl/fixtures.saga-fragment.yaml:4 · covers 1 finding · aws-access-token · no expiry
  last changed in 216dcec72cb8 by Grace Hopper, 2026-10-01
The history is reported only where it is reliable. A shallow clone, which is what most CI systems
check out by default, holds no history behind its boundary commit and attributes every older line
to it, so a line there is reported as unavailable rather than credited to whoever made that commit.
The same repository cloned with --depth 1 prints:
DECISIONS
  a fixture key, issued by nobody
  draugr.saga.yaml:15 · covers 1 finding · aws-access-token · no expiry
  git history unavailable: the line is older than the shallow clone's history; fetch full history

  test fixtures, never deployed
  excl/fixtures.saga-fragment.yaml:4 · covers 1 finding · aws-access-token · no expiry
  git history unavailable: the line is older than the shallow clone's history; fetch full history
An uncommitted line is reported as unavailable too. report.json carries the same record for every
exclusion, matched or not; report schema lists the
fields, and Full history the CI setting that checks out full
history.
Attribution. A suppression from one of these rules carries origin: saga, and the source and
line of the rule, so a reader knows which line of the descriptor to read. A report uses four
values:
origin | what set the finding aside | who to ask |
|---|---|---|
saga | a rule in this descriptor | whoever committed the rule's line, as its git history records |
vex | a claim imported from a supplier's document | the supplier |
tool | a directive in the scanned file, a #nosec, a # nosemgrep or a gitleaks:allow | whoever committed the line |
scanner | the scanner's own configuration, a .trivyignore line or a Grype ignore: rule | whoever owns that file |
Draugr writes the first two and reads the other two from the scanner's own record of what it
excluded, using SARIF's kind where the scanner writes one. It records which party made the claim and does not check the claim: nothing here opens
the supplier's document or reads the comment, so the origin says who to ask and never that the
answer is right.
Neither of the scanner's own is a decision this project recorded. They are listed and counted
under scanner exclusions, never under config.exclude.
Declaring what a suppression means in VEX
reason is prose for whoever reviews the descriptor. A VEX status is a
machine-readable claim your customers' tooling acts on without reading it. They are different
statements, so vex is a separate field rather than something inferred from the other one:
config:
  exclude:
    - rules: ["CVE-2018-18074"]
      reason: "The redirect path that leaks the header is never taken; we pin the host."
      vex:
        status: not_affected
justification: vulnerable_code_not_in_execute_path| Field | Meaning |
|---|---|
status | The claim, from the three below. |
justification | Why the product is not affected, from VEX's fixed vocabulary. Valid only with not_affected. |
status | The claim |
|---|---|
not_affected | No remediation is required regarding this vulnerability. Requires a justification. |
affected | Actions are recommended to remediate or address this vulnerability. |
fixed | These product versions contain a fix for the vulnerability. |
justification is a closed list, because the entire value of the field is that a consumer can act
on it without reading English. These are the five, in the words the OpenVEX specification defines
them in, except where saying only that would not tell two of them apart:
justification | The claim |
|---|---|
component_not_present | The component is not included in the product at all. |
vulnerable_code_not_present | The component is included, but the vulnerable code is not, typically because of how it was configured or built. |
vulnerable_code_not_in_execute_path | The vulnerable code is present and cannot be executed as the product uses it: the product does not call it. |
vulnerable_code_cannot_be_controlled_by_adversary | The vulnerable code does run, and nothing an attacker supplies reaches it. The specification calls this difficult to prove conclusively. |
inline_mitigations_already_exist | Built-in protections completely prevent exploitation by known attack vectors, and a user cannot disable them. |
The same words are on each value in the schema, so an editor shows them beside the completion.
Omit the field and the reason is published as VEX's prose alternative instead, which is valid and
simply less useful to a machine.
Omitting vex entirely is fine. The suppression is then published as affected carrying your
reason. True, since you did find it and did decide to accept it. Draugr will not read the reason to
work out whether you meant not_affected: that is a claim of safety made on your behalf, inferred
from prose, and published over your name.
under_investigation is not accepted here, because it is what an untriaged finding already reports, and
claiming it for something you have suppressed says the matter is both open and settled.
An expiry is enforced, not advisory. On the day after expires the exclusion stops suppressing
and the finding comes back, with the report saying the exclusion lapsed, so a finding that used to
be accepted does not simply reappear unexplained:
ACCEPTED
  config.exclude  4 findings suppressed · 1 expired and no longer suppressing
                  expired 2026-08-14 · draugr.saga.yaml:9 · Upstream fix lands in v2.4…
An exclusion accepted "until the upstream fix lands" otherwise has nothing that brings the finding back, which is how a suppression mechanism decays into a way of never seeing something again. A date that cannot be parsed is rejected at load: it would suppress indefinitely while the descriptor claims otherwise.
paths and rules glob differently, on purpose. In paths, * stops at a directory
separator, so *.md matches README.md but not docs/README.md. They really are paths. In rules
it doesn't, because a rule id is an opaque string and the compound ones are the ones worth matching:
a package name contains slashes, so a wildcard that stopped at / couldn't express "this rule,
whichever package".
A wide pattern is safe to use because it is loud. Nothing is deleted, so rules: ["*"]
reports config.exclude: N findings suppressed and every one of them sits in the SARIF with
your justification. An exclusion that swallowed more than you meant shows up in the count.
A rule that matched nothing gets a block of its own. It is doing nothing and reads exactly like
one that is working, and the cause is usually a typo, a rule id that moved, a finding somebody fixed
and forgot to stop excusing, or a paths pattern that does not mean what it looks like. The rule is
named rather than counted, because the thing to do about it is open the descriptor and edit that
line:
UNMATCHED
  config.exclude  paths tests* · test files that are not deployed
That one is the paths glob rule above, met in the wild: tests* stops at the separator, so it
matches a file called testsuite.go and nothing inside tests/. tests/ is the spelling that
excludes the directory.
Run without --controls or --components to check which rules match nothing. A narrowed run lists
no exclusion rule under Unmatched, because a rule matches by rule id and path and can apply to a
control or a component the run left out.
The report counts three kinds of acceptance separately, because they have different people at the end of them and one total could only support the weakest:
ACCEPTED
  config.exclude     5 findings suppressed
  VEX                1 finding excused
  scanner exclusions 2 findings suppressed
Who set each one aside is asked of the evidence rather than of a scan somebody is reading to find
out what to fix, so --evidence adds it: the author of each supplier's statement on the row, and
each exclusion's git history in the DECISIONS block shown above.
ACCEPTED
  config.exclude     5 findings suppressed
  VEX                1 finding excused · 1 asserted by ACME Security <sec@acme.example>
  scanner exclusions 2 findings suppressed
scanner exclusions is every finding a scanner set aside on its own, with nothing in this
descriptor asking it to: a # nosemgrep, a #nosec or a gitleaks:allow beside the line, or a
rule in a file the scanner reads such as .trivyignore or .grype.yaml. Draugr reports them rather
than letting them disappear, because a finding somebody excluded and a finding nobody ever had look
identical once the scanner has dropped it.
An exclusion the scanner records in no output format cannot be reported, such as a
#trivy:ignore comment in an IaC file or an entry in .gitleaksignore. Where a scanner reports
only some of its exclusions, its page in the catalog says which.
config.exclude keeps the finding and the reason in every case.
It is the weakest of the three, and that is why it is a row of its own rather than part of a total. Both kinds were written outside the descriptor, neither carries an author or a date, and neither went past a reviewer. A single count would let that hide inside the two that did.
Which of the two a finding is stays on the finding, as origin: tool or origin: scanner, because
they send you to different people: whoever committed the line, or whoever owns the file of
exclusions. --evidence names the files.
When both paths and rules are set, a finding must match both. That's the narrow reading,
"this rule, in this place", and the safe one: the alternative would quietly widen ignore the
fixture's fake key into ignore that rule everywhere.
A reason is required because an exclusion without one is indistinguishable from an oversight six
months later, and a reviewer has nothing to judge. It's the cheapest guard against a scanner being
quietly defanged. An entry with neither paths nor rules is rejected too. It would suppress every
finding in the project.
Findings a scanner suppressed itself (a Semgrep nosem comment, say) keep their own reason and
aren't re-attributed to your Saga.
config.exploitability
Raises a finding's severity by real-world exploitability before it is ranked, so priority reflects what is being exploited rather than only what could be.
config:
  exploitability:
    kev: cache          # path | cache | auto. Omit to leave KEV off
    epss: cache
    epssThreshold: 0.5  # optional; default 0.5
maxAge: 24h # optional; default 24h| Key | Meaning |
|---|---|
kev | CISA's Known Exploited Vulnerabilities catalog. A CVE on it becomes critical, whatever it was. |
epss | FIRST's EPSS scores. A CVE at or above epssThreshold is raised one level. |
epssThreshold | The EPSS probability (0–1) that triggers the bump. Zero disables it while leaving KEV in force. |
maxAge | How old a cached feed may be before auto refetches it and a scan warns, and before govulncheck stops reading the local Go vulnerability database. draugr feeds status --saga and feeds update --saga apply the same limit. A Go duration; 0s never expires a copy. |
KEV wins where both apply: observed exploitation outranks a prediction about it. Either signal works without the other. Set one key and omit the other.
Where the data comes from. kev and epss each take three kinds of value:
| Value | Behavior |
|---|---|
| a path | that file. Touches neither the cache nor the network, the air-gapped route |
cache | reads ~/.draugr/feeds; never fetches. Errors if nothing is cached |
auto | reads the cache, fetching when it is missing or older than maxAge |
Populate the cache with draugr feeds update. In CI, make that its own
step and use cache, so a feed outage fails where it happened rather than producing a scan that
ranked everything as though nothing were exploited.
A scan started by an assistant through draugr mcp reads auto as
cache. It never fetches, and a feed the cache does not hold fails the call with an error naming
the draugr feeds update command that fetches it.
Flags override this block, but only the ones you actually type: --kev, --epss and
--epss-threshold. Passing --epss-threshold 0.5 beats a descriptor saying 0.1 even though
0.5 is also the flag's default; not passing it leaves the descriptor's value alone.
Raise maxAge on a runner deliberately pinned to a known copy of the data, reproducing last
quarter's verdict requires last quarter's feed.
See prioritization for what the signals mean and how to choose a threshold.
VEX (config.vex)
Names the party making the claims in a generated VEX document
(--report vex), and the product they are about.
project: acme-api         # what you call this internally
release:
  version: "2.4.0"

config:
  vex:
    author: "Acme Ltd <security@acme.example>"   # who is making the claim
product: "pkg:oci/acme/api" # what a consumer will match on| Field | The question it answers |
|---|---|
author | Who is making this claim? An organization, ideally with a way to reach them. |
product | What will a consumer's tooling look this up by? An IRI; a package URL is conventional. |
release and config.vex are not the same thing
They describe the same product and rarely with the same string, which is the part worth being careful about.
release is what you call this internally. It names what Draugr is qualifying, and it is
what appears at the top of your report.
config.vex is how the outside world refers to it. A VEX statement is matched by product
identifier: a consumer applies it when the identifier equals what their SBOM calls the thing they
are scanning. That is usually not your release name. It is an image reference, a package URL, a
digest.
Both fields are optional, and the defaults produce a valid document rather than a publishable one:
| Unset | Falls back to | Why that is not enough |
|---|---|---|
author | project | A project name is not a party. A consumer with a question about your claim needs somebody to ask. |
product | pkg:generic/<project>@<release.version>, without @ where no version is given | Synthesized from your descriptor. pkg:generic/ says so plainly. Unless a consumer happens to call your product exactly that, nothing will match. |
A document nothing matches fails silently. A consumer cannot tell that a statement was meant for it, so a wrong identifier does not error. It is read, understood, and applied to nothing. This is the single field most worth checking against a consumer's SBOM before you publish.
Versions track the release
A VEX statement is about a version of a product: not_affected in 2.3 says nothing about 2.4.
Leave the version out of product and Draugr appends release.version. This is the recommended
form, and it cannot go stale, the identifier moves when the release does.
project: acme-api
release: { version: "2.4.0" }
config:
  vex:
    product: "pkg:oci/acme/api"     # → pkg:oci/acme/api@2.4.0
A version you write yourself is kept exactly as given, because pinning is sometimes what you want:
product: "pkg:oci/acme/api@sha256:0123…" # a digest, left aloneThat escape hatch has a cost worth stating: a literal version does not follow the release.
Write pkg:oci/acme/api@2.4.0, ship 2.5.0, and the document keeps claiming 2.4.0. Prefer the
version-less form unless you are pinning to something immutable.
Qualifiers and a subpath are preserved. The version is inserted where the package-URL specification
puts it (pkg:type/name@version?qualifiers#subpath). A product that is not a package URL is left
untouched, since VEX identifies a product by IRI and a purl is only the convention.
Reading a supplier's VEX (components[].vex, config.vexSources)
The other direction from config.vex. That describes the document Draugr writes about your
product; these list documents Draugr reads about somebody else's, applying their statements to
your findings.
config:
  vexSources:                       # applies to every component
    - url: https://platform.internal/vex/current.openvex.json
components:
  - name: payments-api
    vex:                            # applies to this component only
      - path: vendor/acme-api.openvex.json
      - repository:
          url:  https://github.com/acme/security
          ref:  v2026.08
          path: vex/api.openvex.json
Each entry names exactly one of three sources. Naming two is an error rather than a precedence rule: a source carrying both a path and a URL is a descriptor whose author believed two different things about where the document lives.
| Field | Meaning |
|---|---|
path | A file on disk, resolved relative to where Draugr runs, not to the descriptor and not to the repository, the same rule hosts[].spec.path follows. |
url | Fetched over HTTPS each run. The report records the URL, the fetch time and the digest of what came back. |
repository.url | A git repository holding the document. Cloned with whatever credentials git already has; Draugr stores none, so no token belongs here. |
repository.ref | Branch, tag or commit. Optional, the default branch otherwise. Worth pinning for a claim you gate on; the report records the commit actually read either way. |
repository.path | The document's path inside the repository. Required, and it may not climb out of it. |
Scope. A component's own sources apply to its findings; config.vexSources applies to every
component. Statements are matched by package identifier regardless, so listing a source widens which
findings are considered. It does not let a statement claim more than it says.
Effect. Only not_affected and fixed suppress. affected and under_investigation are
recorded and reported but change nothing, because they concede exposure rather than excusing it.
Where config.exclude already covers a finding, your own reason stands.
Attribution. A suppression from a claim carries origin: vex, the document's author, and the
date the claim was asserted, in the console, in report.json and in the SARIF property bag. That
separation is the reason to read a document rather than retype it: a copied not_affected becomes a
decision you are answerable for, while an imported one stays a claim somebody else made.
A source that cannot be read fails the run. Not a warning and never a skip: a scan that quietly dropped a supplier's analysis would report more findings than the last one with nothing saying why, which reads exactly like a codebase that got worse.
SBOM generation
config:
  sbom:
    enabled: true
    format: cyclonedx-json   # defaults to cyclonedx-json
    scope: component         # component (default) | project | both
Produces one Software Bill of Materials per distinct
repository and image in the Saga, an inventory of what each one contains. Requires
Syft (draugr tools install syft). Syft runs with
SYFT_CHECK_FOR_APP_UPDATE=false, so it does not ask toolbox-data.anchore.io whether a newer Syft
exists.
Choosing a format. Both open specifications, each in both of its standard encodings, pick whichever the thing consuming the document reads:
format | Written as | Media type |
|---|---|---|
cyclonedx-json (default) | sbom-<component>-<target>.cdx.json | application/vnd.cyclonedx+json |
cyclonedx-xml | sbom-<component>-<target>.cdx.xml | application/vnd.cyclonedx+xml |
spdx-json | sbom-<component>-<target>.spdx.json | application/spdx+json |
spdx-tag-value | sbom-<component>-<target>.spdx | text/spdx |
Why CycloneDX is the default. Both are open standards and neither is going away, so the default
is decided by what a document is likely to be used for rather than by seniority. CycloneDX
(ECMA-424) composes: a document can carry nested components and state how complete it is, so it
answers "what is in this project" and not only "what is in this repository". It is also what most
security tooling reads first, and the format VEX is expressed in. SPDX (ISO/IEC 5962) is the name a
procurement questionnaire or license-compliance process is more likely to ask for. Set format: spdx-json when that is who the document is for.
Syft can emit more, its own syft-json, GitHub's dependency-snapshot format, a bare PURL list, but
those are either vendor-specific or not an SBOM, so Draugr doesn't offer them. Every document it
produces is one a third party can read. An unsupported value is rejected when the Saga loads, naming
the four, rather than failing after the scan has run.
It is not a control, and this is deliberate. Every control checks something and returns a
verdict the gate acts on. An SBOM finds nothing, so it has no verdict to give; a control row
that always reads "pass" without having looked is exactly the meaningless green Draugr exists
to remove. So SBOMs are evidence: they never appear in the controls table and never affect
pass or fail, and the console reports what was written where it reports the rest of what the run
did, under --evidence:
EVIDENCE
  sbom        2 documents (cyclonedx-json)
report.json lists each document under sboms with its file and digest,
and each target whose inventory failed, with the reason.
One document per target, or one per product
scope decides what each document covers.
scope | Produces |
|---|---|
component (default) | one document per distinct repository and image |
project | one document covering the whole release |
both | the per-target documents and the assembled one |
Why this exists. An SBOM is asked for per product. A customer questionnaire, EO 14028 and the CRA all want the bill of materials of the thing you shipped. Draugr scans per repository and image, so a project with four repositories and three images produces seven documents and no answer to the question being asked.
config:
  sbom:
    enabled: true
    scope: project
EVIDENCE
sbom 1 project document (cyclonedx-json)The assembled document is written as sbom-project.cdx.json. Its root component is the release,
with one node per Saga component beneath it, one per repository or image beneath that, and the
packages beneath those.
This is assembly, not merging. A generic merge tool has a pile of documents and has to guess how they relate. Draugr is handed a release containing named components containing named targets. The hierarchy is declared, so it does not have to be inferred.
That matters for the question a merge usually destroys. When requests 2.19.1 appears in three
components, deduplicating to one entry answers what do we ship and loses who ships it, which
is what a triager needs the moment a CVE lands; keeping three entries answers the second and makes
any consumer counting packages report a meaningless number. So Draugr keeps one entry per
package and a dependency graph saying which targets contain it, and both questions are
answerable from the same document. Two versions of one library stay two packages.
scope: project replaces the per-target documents rather than adding to them. You asked for a
document covering the product. Use both when you want the parts as evidence for the whole.
CycloneDX only. project and both require format: cyclonedx-json and say so if it is
something else. SPDX expresses containment through relationships and could carry this, but
assembling it correctly is different work, and a half-right SPDX document would be worse than
declining because nothing about it would look wrong.
Where the documents go. -o <dir> writes them beside report.json and results.sarif, and any
configured publisher delivers them alongside its reports, including with no reports at
all, if the inventory is the only output you want. Filenames are sbom-<component>-<target> plus
the suffix for the format, with the target slugged so two images in one component can't collide.
There is no --format sbom: a run produces one document per target, and a format that writes
several files has no meaning on stdout.
If Syft is missing, the scan fails. Generation errors are reported under (sbom) and make the
run incomplete, exactly as a missing scanner does. You asked for an inventory and didn't get one,
and silence would let you believe you had it. --allow-scan-errors accepts the partial result if
that's what you want; the error is still reported either way.
Deduplicated by target: several controls scan the same repository, and its inventory is one document however many touched it. The same image referenced by two components is likewise one.
fragments
Merge other files into this descriptor. See split a Saga across files for the monorepo shape.
fragments:
  # Local: a path relative to the file that names it.
  - path: "**/draugr.saga-fragment.yaml"

  # Remote: the same shape as a repository, plus which files to read.
  - url: https://github.com/acme/platform.git
    revision: v2.4.0
path: "components/**/draugr.saga-fragment.yaml"| Field | Meaning |
|---|---|
path | Required. Which files to read. Globs use the same dialect as paths and ignore, * within a segment, ** across them. Relative to the file that names it, so ../shared/x.saga-fragment.yaml works. |
url | A git repository to read from. Omit for a local path. |
revision | Branch, tag or commit. Required with url, and not defaulted. See below. |
A fragment adds scope, adds attributed suppressions, or contributes a setting that can only add
findings. It cannot change policy. It may carry components, config.exclude, further
fragments, and the short list of control settings in the table below. Nothing else. release,
config.gate, a component's own controls and any other control setting are rejected, naming the
rule. That is what makes a
fragments: line safe to review: pulling a file in can never quietly lower your gate or switch a
control off, and the worst it can do is add suppressions, which are individually attributed and
counted in the report.
| Setting a fragment may contribute | What it does |
|---|---|
config.controls.provenance.signers | Adds signers to the descriptor's own, so an organization can declare who signs what once and include it everywhere. |
A contributed setting is appended, never assigned: the descriptor's own values stay, and the
fragment's are added after them. report.json records which file each one came from, under
descriptor.contributed, so a reviewer can find out which included file expects an identity nobody
reading the descriptor declared. The same map names the configuration file behind each control
default that reached the descriptor, keyed by the setting's path, as secrets.gitleaks.history;
the report schema lists both kinds of key.
config.controls.provenance.unmatched and trustRoot are not on the list. Whether an
uncovered image is a gap or a fact about the ecosystem, and which certificate roots are trusted,
stay with whoever answers for the verdict.
Components merge by name, and their surfaces union. exposure, criticality, builtBy and
each label key take the value of the first file that sets them, the root descriptor first; the
guide gives the full order.
A pattern that matches nothing is an error. Somebody wrote the line on purpose, so silence from it is indistinguishable from a typo, and the result would be a descriptor scanning less than it claims. If a product genuinely has no components on one cloud, do not list that pattern.
A remote fragment must name a revision. Defaulting to the repository's default branch would make your gate change with no commit in your own repository. A tag is fine; the commit it resolved to is recorded, so a tag that moves is visible afterwards.
Fragments are files named *.saga-fragment.yaml (or .yml), with their own
schema. A fragment has no release:,
so validating one against the Saga's schema would report every valid fragment as broken. draugr validate checks a fragment on its own, and draugr schema --fragment prints the schema this build
enforces.
draugr validate azure.saga.yaml --resolved # the merged descriptor, with sourcesreferences
Links to manual or human-performed controls (threat model, architecture diagram, …):
references:
  - type: ThreatModel
    link: https://example.com/threat-model